BenchLeader

LLM API price statistics

Data as of 2 Nov 2026 · last updated · by BenchLeader

The median ranked model on BenchLeader costs $0.50 per 1M input tokens and $2.00 per 1M output tokens (239 ranked models with a list price). Blended at three input tokens to one output token, the median is $0.85 per 1M tokens, and output costs a median 4× input. The cheapest model scoring 65+ on the BenchLeader Index is GPT-6.1 Terra at $1.00/$5.00.

Want your own number? The LLM cost calculator prices a month of your usage on every ranked model at these list prices.

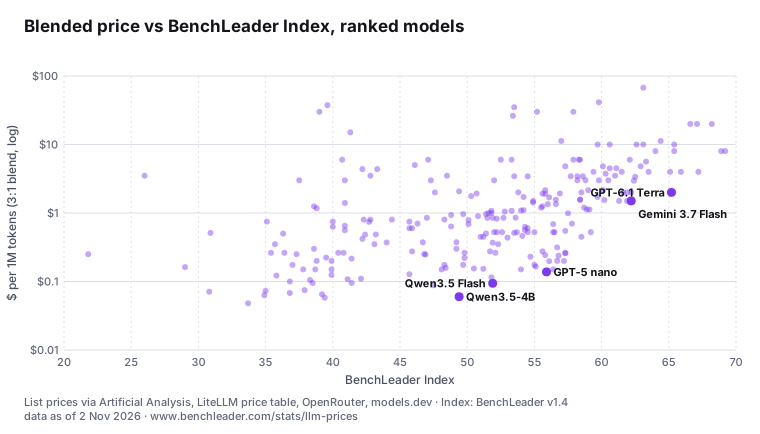
Blended price vs BenchLeader Index, ranked modelsThe median ranked model on BenchLeader costs $0.50 per 1M input tokens and $2.00 per 1M output tokens (239 ranked models with a list price).Blended price vs BenchLeader Index, ranked models$0.01$0.1$1$10$1002025303540455055606570BenchLeader Index$ per 1M tokens (3:1 blend, log)Claude Opus 5.5: 69.2, $8Gemini 4 Carbon: 68.9, $8GPT-6 Astra: 68.2, $20GPT-6.1 Sol: 67.2, $4Claude Fable 5.1: 67.1, $20Claude Fable 5: 66.6, $20Gemini 4 Argon: 65.9, $4GPT-5.6 Sol: 65.4, $8Claude Opus 5: 65.4, $10GPT-6.1 Terra: 65.2, $2Claude Sonnet 5.5: 65.1, $4GPT-5.5: 64.4, $11.25Muse Wonder: 64.0, $8GPT-6 Sol: 63.5, $4GPT-5.4: 63.3, $5.625Claude Opus 4.7: 63.1, $10GPT-5.4 Pro: 63.1, $67.5GPT-5.3-Codex: 62.9, $4.813Claude Opus 4.6: 62.6, $10Gemini 3.5 Flash: 62.5, $3.375Qwen3.6 Max: 62.4, $2.965Gemini 3.7 Flash: 62.2, $1.5Muse Spark 1.1: 62.2, $2Kimi K3: 62.1, $6Gemini 3.8 Flash: 61.9, $1.5Muse Spark 1.3: 61.9, $2Muse Spark 1.2: 61.6, $2Kimi K3.1 Pro: 61.5, $4Gemini 3.6 Flash: 61.3, $1.5GPT-5.6 Terra: 61.1, $4.5o3: 61.0, $3.5Gemini 3.1 Pro: 60.6, $4.5Claude Opus 4.8: 60.6, $10Grok 4.6: 60.5, $3Qwen3.7: 60.3, $3.75GLM-5: 60.2, $1.55GPT-5.2: 60.1, $4.813GLM 5.2: 60.1, $2.15Grok 4.5: 59.8, $3GPT-5 Pro: 59.8, $41.25Claude Opus 4.5: 59.7, $10Kimi K2.6: 59.7, $1.713Claude Sonnet 5: 59.4, $4DeepSeek V4.1 Flash 1017: 59.2, $0.525Qwen3.6 Plus: 59.1, $1.125GLM 5.3: 59.0, $2.15Gemini 3 Flash: 58.9, $1.125Qwen3.8 Max: 58.8, $3Kimi K2.5: 58.7, $1.2GPT-5-Codex: 58.6, $3.438GPT-5.6 Luna: 58.5, $0.45Muse Spark Open 816B A42B: 58.5, $2Grok 4: 58.4, $6Grok 4.20: 58.4, $1.563Grok 4.20 Multi-Agent: 58.4, $1.563Claude Sonnet 4.6: 58.3, $6Grok 4.7: 58.2, $3GPT-5: 58.2, $3.438Claude Opus 4.1: 57.9, $30Claude Sonnet 4.5: 57.9, $6Qwen3.7 Plus: 57.8, $0.7GPT-5.1: 57.7, $3.438DeepSeek V4 Pro: 57.5, $0.99MiMo-V2.6-Pro: 57.3, $0.548DeepSeek V4 Flash: 57.3, $0.262Qwen3.5 Plus: 57.3, $0.258GPT-5.2-Codex: 57.3, $4.813Claude Haiku 5.5: 57.2, $0.2GPT-5.5 Instant: 57.0, $11.25o4-mini: 56.9, $1.925GLM 5.3 Flash: 56.8, $0.238GPT-6 Luna: 56.7, $0.2DeepSeek V3.2: 56.7, $0.315Grok 4.3: 56.6, $1.563Qwen3.5 397B A17B: 56.6, $1.35MiniMax M2.7: 56.5, $0.525MiniMax M3: 56.4, $0.525GPT-5 mini: 56.4, $0.688Step 3.5 Flash: 56.4, $0.15GPT-5.4 Mini: 56.1, $1.688Gemma 4 26B A4B: 56.1, $0.198Qwen3.6 27B: 56.0, $1.35GPT-5 nano: 55.9, $0.138GLM 5.1: 55.8, $2.15Hy3: 55.8, $0.243GLM 5V Turbo: 55.8, $1.9Grok 4.1 Fast: 55.6, $0.275DeepSeek V3.1 Terminus: 55.6, $1.918Hy4: 55.6, $1.251Nemotron 3 Ultra 550B A55B: 55.5, $1.2Claude Opus 4: 55.2, $30MiMo-V2.5: 55.1, $0.165MiMo-V2.6-Flash: 55.0, $0.175MiniMax-M2.1: 55.0, $0.525Step 5 Preview: 54.9, $1.425MiMo-V2.5-Pro: 54.9, $1.5Qwen3.8-Flash-Next: 54.7, $0.23Gemini 2.5 Pro: 54.5, $3.438Beam 1.0 501B A23B: 54.5, $0.6Muse Glimmer: 54.5, $0.525Gemini 3.1 Flash Lite: 54.3, $0.563Qwen3 Max: 54.3, $0.628Kimi K2.7 Code: 54.2, $1.713Qwen3.5-122B-A10B: 54.2, $1.1GPT-5.4 Nano: 54.1, $0.463Qwen3.8 27B: 54.0, $1.088MiMo-V2-Flash: 54.0, $0.15Muse Spark Open: 53.8, $2MiniMax M2.5: 53.7, $0.525DeepSeek V3.2 Speciale: 53.6, $0.855Qwen3 VL 235B A22B Instruct: 53.5, $0.513o3-pro: 53.5, $35Nova 2.0 Pro Preview: 53.5, $3.438o1: 53.4, $26.25Claude Sonnet 4: 53.3, $6Kimi K2 Thinking: 53.3, $1.075Step 3.7 Flash: 53.0, $0.438Mistral Large 4: 52.8, $1.05Gemini 2.5 Flash: 52.7, $0.85MiniMax-M2: 52.6, $0.525Grok 3: 52.5, $6Qwen3-Next 80B A3B: 52.3, $0.35Inkling Small: 52.2, $0.525Qwen3.5-27B: 52.2, $0.825MiniMax M3.1 Flash: 52.1, $0.262Solar Pro 4: 52.0, $0.525Qwen3.8 2.4T A95B: 52.0, $3Qwen3 235B A22B 2507: 51.9, $0.368Qwen3.5 Flash: 51.9, $0.094Qwen3.6 35B A3B: 51.9, $0.848GLM 4.7: 51.8, $1Kimi K2 0905: 51.8, $1.075Ling 3.0 Flash: 51.8, $0.115Grok 4 Fast: 51.7, $0.275GLM-4.5: 51.6, $1Gemini 3.5 Flash Lite: 51.5, $0.85Qwen3 32B: 51.4, $0.502GLM-4.6: 51.4, $0.963GLM 4.7 Flash: 51.2, $0.153Nemotron 3 Super 120B A12B: 51.2, $0.45Ling 3.1 Flash: 51.0, $0.45GLM 4.5V: 50.8, $0.9o3-mini: 50.7, $1.925Qwen3.5-9B: 50.5, $0.155Inkling: 50.3, $1.763Qwen3.5-35B-A3B: 50.1, $0.688Nemotron 3.5 Super VL 120B A12B: 50.1, $0.788gpt-oss-120b: 49.8, $0.262Gemma 4 31B: 49.8, $0.22Gemini 2.5 Flash Lite 09: 49.7, $0.175MiniMax-M1: 49.7, $0.963DeepSeek R1 0528: 49.4, $2.075Qwen3.5-4B: 49.4, $0.06Mercury 2: 49.2, $0.375Seed-OSS-36B-Instruct: 49.2, $0.3Qwen3 Coder 480B: 48.8, $0.635Nova 2 Lite: 48.8, $0.935GPT-4.1: 48.5, $3.5Qwen-Plus: 48.4, $0.158Mistral Medium 3.1: 48.3, $0.8Gemini 2.5 Flash-Lite: 48.3, $0.175Qwen3 30B A3B 2507: 48.1, $0.15Claude Haiku 4.5: 47.6, $2Nemotron 3 Nano 30B A3B: 47.5, $0.088Mistral Medium 3.5: 47.3, $3Claude 3.5 Sonnet: 47.1, $6Ring-2.6-1T: 47.0, $0.85Ling Flash 2.0: 46.9, $0.248Qwen3 14B: 46.8, $0.251GLM-4.5-Air: 46.7, $0.373GPT-4.1 mini: 46.3, $0.7Nova Premier: 46.1, $5Command A+: 45.9, $0.6Nemotron 3.5 Super VL: 45.9, $0.275Mistral Large 3: 45.7, $0.75Beam 1.0: 45.7, $0.6gpt-oss-20b: 45.7, $0.128Mistral Medium 3: 44.4, $0.8Qwen3.6 Flash: 44.0, $0.371GPT-4o: 43.3, $4.375Qwen2.5 72B: 43.2, $0.485Reka Flash: 43.1, $0.35Jamba 1.5 Large: 42.8, $3.5Devstral 2: 42.8, $0.8Qwen2.5 Coder 32B Instruct: 42.7, $0.745Qwen3 Coder Next: 42.4, $0.483R1 Distill Llama 70B: 42.3, $0.8Llama 4 Maverick: 42.2, $0.418Command A: 42.2, $4.375Mistral Small 3.2: 42.1, $0.11Nemotron 3.5 Lightning: 41.4, $0.095DeepSeek-R1-Distill-Qwen-14B: 41.4, $0.216GPT-4 Turbo: 41.3, $15Granite 4.2 8B: 41.1, $0.108Nova Pro: 40.9, $1.4Llama 3.1 70B: 40.9, $0.56Mistral Large 2: 40.9, $3Gemma 2 27B: 40.9, $0.65Solar Pro 3: 40.8, $0.262Mistral Large 24.02: 40.7, $6Mistral Small 4: 40.4, $0.262Llama 3.3 70B: 40.0, $0.628Magistral Small 1.2: 40.0, $0.75Gemma 3 27B: 39.9, $0.15Ministral 3 14B: 39.9, $0.2Qwen2.5 7B Instruct: 39.9, $0.125GPT 4 0613: 39.6, $37.5Phi-4: 39.5, $0.223Mistral Small 3: 39.4, $0.058Nova Micro: 39.2, $0.065Claude 3 Opus: 39.0, $30Llama 3-70B: 38.8, $1.175Qwen3 8B: 38.8, $0.2Ministral 3 8B: 38.7, $0.15Llama 4 Scout: 38.6, $0.3GPT 3.5 Turbo 1106: 38.6, $1.25Mistral Small 3.1: 38.5, $0.095Nova Lite: 38.3, $0.105Gemma 3 12B: 37.9, $0.075Ministral 8B: 37.8, $0.15Mixtral 8x22B Instruct: 37.5, $3Jamba 1.5 Mini: 37.3, $0.25GPT-4.1 nano: 37.0, $0.175Ministral 3 3B: 36.8, $0.1DeepSeek-R1-0528-Qwen3-8B: 36.8, $0.068Magistral Small: 36.4, $0.262Claude 3 Haiku: 36.3, $0.5Llama 3.2 3B Instruct: 35.8, $0.122Llama 3.2 Instruct 11B (Vision): 35.7, $0.35GPT-4o mini: 35.4, $0.262GPT 3.5 Turbo 0125: 35.1, $0.75Llama 3-8B: 35.0, $0.073Gemma 3 4B: 34.9, $0.063Llama 3.1 8B: 33.7, $0.048Mixtral 8x7B: 30.9, $0.513Llama 3.2 1B Instruct: 30.8, $0.071Mistral 7B v0.3: 29.0, $0.162Jamba Large 1.6: 26.0, $3.5Jamba Mini 1.6: 21.8, $0.25GPT-6.1 TerraGemini 3.7 FlashGPT-5 nanoQwen3.5 FlashQwen3.5-4BList prices via Artificial Analysis, LiteLLM price table,OpenRouter, models.dev · Index: BenchLeader v1.4data as of 2 Nov 2026 · www.benchleader.com/stats/llm-prices
The median ranked model on BenchLeader costs $0.50 per 1M input tokens and $2.00 per 1M output tokens (239 ranked models with a list price). Each dot is a ranked model; named dots are the cheapest in each Index tier. Chart image (SVG)

Key statistics

Each statistic has its own link (#) to cite it directly.

  • The median ranked model costs $0.50 per 1M input tokens and $2.00 per 1M output tokens, across 239 ranked models with a list price (BenchLeader, 2 Nov 2026). #
  • The median blended price (three input tokens to one output token) is $0.85 per 1M tokens (BenchLeader, 2 Nov 2026). #
  • Output tokens cost a median 4× as much as input tokens (BenchLeader, 2 Nov 2026). #
  • The cheapest ranked model scoring 65+ on the BenchLeader Index is GPT-6.1 Terra by OpenAI, at $1.00 input and $5.00 output per 1M tokens; the tier's median is $8.00 blended (BenchLeader, 2 Nov 2026). #
  • The cheapest ranked model scoring 60–65 on the BenchLeader Index is Gemini 3.7 Flash by Google, at $0.75 input and $3.75 output per 1M tokens; the tier's median is $4.00 blended (BenchLeader, 2 Nov 2026). #
  • The cheapest ranked model scoring 55–60 on the BenchLeader Index is GPT-5 nano by OpenAI, at $0.05 input and $0.40 output per 1M tokens; the tier's median is $1.35 blended (BenchLeader, 2 Nov 2026). #
  • Among ranked models scoring 60–65, blended prices run from $1.50 to $67.50 per 1M tokens, a 45× spread for similar Index scores (BenchLeader, 2 Nov 2026). #
  • 3 ranked models are on an announced launch price: Gemini 4 Argon until 30 Nov 2026, Gemini 3.6 Flash until 31 Dec 2026 and Gemini 3.8 Flash until 31 Dec 2026 (BenchLeader, 2 Nov 2026). #

Cheapest model at each quality tier

Ranked models grouped by BenchLeader Index. Blended price assumes three input tokens for every output token.

Index tierModelsCheapest modelInput / output per 1MBlendedTier median (blended)Tier max (blended)
65+11GPT-6.1 Terra OpenAI$1.00 / $5.00$2.00$8.00$20.00
60–6527Gemini 3.7 Flash Google$0.75 / $3.75$1.50$4.00$67.50
55–6056GPT-5 nano OpenAI$0.05 / $0.40$0.138$1.35$41.25
50–5553Qwen3.5 Flash Alibaba$0.029 / $0.287$0.094$0.825$35.00
45–5030Qwen3.5-4B Alibaba · open weights$0.03 / $0.15$0.06$0.487$6.00

Today's prices of 2026 releases, by release month

Current list prices of the ranked models released each month. This is a snapshot of today's prices grouped by release date, not a price history: models launched in different months differ in size and purpose.

ReleasedRanked models with a priceMedian input per 1MMedian output per 1M
January 2026 · small sample3$0.15$0.60
February 202617$0.31$2.40
March 202610$0.40$2.00
April 202616$0.975$3.30
May 2026 · small sample7$1.50$7.50
June 2026 · small sample7$0.95$4.00
July 202613$1.00$4.05
August 202616$0.555$2.24
September 202615$2.00$6.00
October 202615$0.57$1.44

Launch prices with an end date

Ranked models whose provider has announced the current price ends. The figures above use today's price.

ModelBlended nowUntilBlended afterSource
Gemini 4 Argon Google$4.0030 Nov 2026$8.00provider
Gemini 3.6 Flash Google$1.5031 Dec 2026$3.00provider
Gemini 3.8 Flash Google$1.5031 Dec 2026$3.00provider

How these numbers are made

239 ranked models (those with a BenchLeader Index) have a list price; prices are per million tokens, at each model's best-scoring configuration. The blended price weights input three to one, the mix of a typical chat or agent turn. Cached input, batch discounts and coding plans are not counted. Full sourcing is in the methodology.

This page is a snapshot of today's list prices; how the price of each quality level has fallen since mid-2024 is on LLM price trends. For the long run, Epoch AI estimates the cost of reaching a given level of performance has fallen about 47% per quarter since 2023 (The plunging price of thought).

Cite these statistics

List prices are each provider's published rates, read via Artificial Analysis, LiteLLM price table, OpenRouter, models.dev. They are shown here with attribution and are not offered for reuse; BenchLeader's own figures on this page are the Index scores and the medians. Cite the page below.

Citation

BenchLeader, “LLM API price statistics”, data as of 2 Nov 2026, https://www.benchleader.com/stats/llm-prices.

Questions people ask

How much does an LLM API cost per million tokens?
The median ranked model on BenchLeader costs $0.50 per 1M input tokens and $2.00 per 1M output tokens (239 ranked models with a list price). Blended at three input tokens to one output token, the median is $0.85.
What is the cheapest high-quality LLM?
GPT-6.1 Terra by OpenAI is the cheapest ranked model scoring 65+ on the BenchLeader Index, at $1.00 input and $5.00 output per 1M tokens.
Why do output tokens cost more than input tokens?
Generating a token takes a full pass of the model for each token, while input is processed in parallel. Across ranked models, output costs a median 4× input.
Are LLM prices falling?
This page is today's list prices. For how the price of a given quality level has fallen since mid-2024, see LLM price trends (/stats/llm-price-trends). Over the longer run, Epoch AI estimates that the cost of reaching a given level of performance has fallen about 47% per quarter since 2023 (“The plunging price of thought”).
Related: LLM cost calculator, cheapest models, best value models, best cheap LLM, coding plans compared, all statistics.