How fast are LLMs? Speed statistics
Data as of 2 Nov 2026 · last updated · by BenchLeader
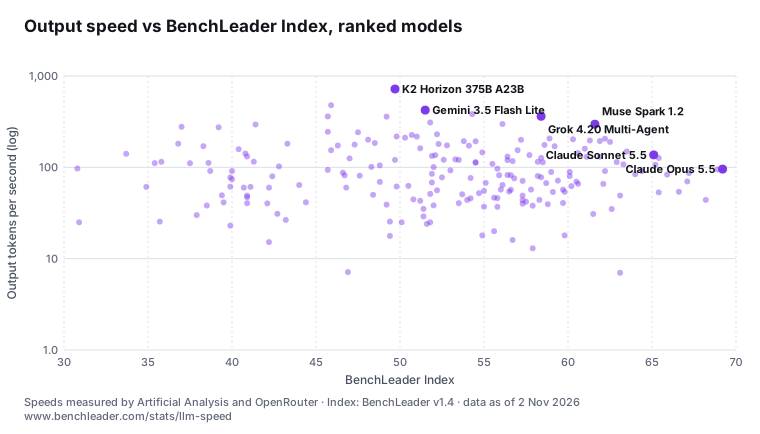
The median ranked model on BenchLeader generates about 83 output tokens per second and starts answering in a median 1.0 s (time to first token); measured by Artificial Analysis and OpenRouter. The fastest model BenchLeader tracks is Celeris-1 at about 1,700 tokens per second (Artificial Analysis). Among models scoring 60 or more on the BenchLeader Index, Muse Spark 1.2 is fastest at about 300 tokens per second.
Key statistics
Each statistic has its own link (#) to cite it directly.
- The median ranked model generates about 83 output tokens per second, across 204 ranked models with a measured speed (measured by Artificial Analysis and OpenRouter; BenchLeader, 2 Nov 2026). #
- The median time to first token is 1.0 s, across 187 ranked models (measured by OpenRouter and Artificial Analysis; BenchLeader, 2 Nov 2026). #
- The fastest model BenchLeader tracks is Celeris-1 by Celeris, at about 1,700 tokens per second (Artificial Analysis; BenchLeader, 2 Nov 2026). #
- The fastest ranked model scoring 60 or more on the BenchLeader Index is Muse Spark 1.2, at about 300 tokens per second (Artificial Analysis; BenchLeader, 2 Nov 2026). #
- The lowest time to first token among ranked models scoring 60 or more is GLM 5.2's 0.73 s (OpenRouter; BenchLeader, 2 Nov 2026). #
- The lowest time to first token of any ranked model is Qwen3.5-9B's 0.18 s (OpenRouter; BenchLeader, 2 Nov 2026). #
- Claude Opus 5.5, the BenchLeader Index leader, generates about 96 tokens per second, measured by Artificial Analysis, with a 3.4 s time to first token, measured by OpenRouter (BenchLeader, 2 Nov 2026). #
Fastest model at each quality tier
| Index tier | Models with a speed | Fastest model | Tokens per second | Measured by |
|---|---|---|---|---|
| 65+ | 11 | Claude Sonnet 5.5 Anthropic | 140 | Artificial Analysis |
| 60–65 | 26 | Muse Spark 1.2 Meta | 300 | Artificial Analysis |
| 55–60 | 52 | Grok 4.20 Multi-Agent SpaceXAI | 360 | OpenRouter |
| 50–55 | 44 | Gemini 3.5 Flash Lite Google | 420 | Artificial Analysis |
| 45–50 | 28 | K2 Horizon 375B A23B MBZUAI | 720 | Artificial Analysis |
Fastest models by output speed
Ranked models only (those with a BenchLeader Index). The speed leaderboard also lists models without an Index, which is why the fastest model overall may not appear here.
| # | Model | Index | Tokens per second | Measured by |
|---|---|---|---|---|
| 1 | K2 Horizon 375B A23B MBZUAI | 49.7 | 720 | Artificial Analysis |
| 2 | Nemotron 3.5 Super VL NVIDIA | 45.9 | 480 | Artificial Analysis |
| 3 | Gemini 3.5 Flash Lite Google | 51.5 | 420 | Artificial Analysis |
| 4 | Gemini 3.1 Flash Lite Google | 54.3 | 380 | Artificial Analysis |
| 5 | Grok 4.20 Multi-Agent SpaceXAI | 58.4 | 360 | OpenRouter |
| 6 | Beam 1.0 Reflection | 45.7 | 360 | Artificial Analysis |
| 7 | Mercury 2 Inception | 49.2 | 360 | OpenRouter |
| 8 | Ling 3.0 Flash Ant Group | 51.8 | 310 | Artificial Analysis |
| 9 | GPT-5.4 Mini OpenAI | 56.1 | 300 | Artificial Analysis |
| 10 | Muse Spark 1.2 Meta | 61.6 | 300 | Artificial Analysis |
Quickest to the first token
Ranked models with the lowest time to first token; see the latency leaderboard for all of them.
| # | Model | Index | Time to first token | Measured by |
|---|---|---|---|---|
| 1 | Qwen3.5-9B Alibaba | 50.5 | 0.18 s | OpenRouter |
| 2 | Llama 3.2 1B Instruct Meta | 30.8 | 0.23 s | OpenRouter |
| 3 | Qwen2.5 7B Instruct Alibaba | 39.9 | 0.25 s | OpenRouter |
| 4 | Nemotron 3 Ultra 550B A55B NVIDIA | 55.5 | 0.27 s | OpenRouter |
| 5 | Command A+ Cohere | 45.9 | 0.28 s | OpenRouter |
| 6 | Nemotron 3.5 Lightning NVIDIA | 41.4 | 0.29 s | OpenRouter |
| 7 | Qwen3 30B A3B 2507 Alibaba | 48.1 | 0.30 s | OpenRouter |
| 8 | Granite 4.2 8B IBM | 41.1 | 0.33 s | OpenRouter |
| 9 | Ministral 3 3B Mistral AI | 36.8 | 0.34 s | OpenRouter |
| 10 | Nova Micro Amazon | 39.2 | 0.35 s | OpenRouter |
How these numbers are made
Output speed is the median number of tokens a model generates per second once it starts answering: Artificial Analysis' measured median where it covers a model, otherwise OpenRouter's live-traffic median smoothed over seven days. Time to first token is credited to its measurer in each table; OpenRouter's figure leaves out any thinking phase. Medians are over ranked models (those with a BenchLeader Index), at each model's best-scoring configuration.
Speed depends on the provider serving the model, the load and the prompt, so treat a figure as typical rather than guaranteed. Full sourcing is in the methodology.
Cite these statistics
Speeds are measured by Artificial Analysis and OpenRouter and shown here with attribution; they stay under the measurers' terms and are not offered for reuse. BenchLeader's own figures on this page are the Index scores and the medians. Cite the page below.
Citation
BenchLeader, “LLM speed statistics”, data as of 2 Nov 2026, https://www.benchleader.com/stats/llm-speed.Questions people ask
- How fast are LLMs in tokens per second?
- The median ranked model on BenchLeader generates about 83 output tokens per second (measured by Artificial Analysis and OpenRouter). The fastest tracked model, Celeris-1, reaches about 1,700.
- What is a typical time to first token?
- A median 1.0 s across 187 ranked models (measured by OpenRouter and Artificial Analysis). OpenRouter's first-token figure leaves out any thinking phase.
- What is the fastest high-quality LLM?
- Muse Spark 1.2 by Meta: about 300 tokens per second (Artificial Analysis) among ranked models scoring 60 or more on the BenchLeader Index.
- Where do these speeds come from?
- Output speed is Artificial Analysis' measured median where it covers a model, otherwise OpenRouter's live-traffic median smoothed over seven days; time to first token is mostly OpenRouter's. Each figure is credited to its measurer, whose terms apply; BenchLeader does not relicense them.
Related: speed leaderboard, latency leaderboard, fastest LLM, LLM price statistics, all statistics.