大模型有多快?速度统计
数据截至 2026年11月16日 · 最后更新于 · BenchLeader
BenchLeader 已排名模型的输出速度中位数约为 82 token/秒,开始回答所需时间(首 token 延迟)的中位数为 1.1 秒;数据由 Artificial Analysis 和 OpenRouter 测量。BenchLeader 追踪的最快模型是 Celeris-1,约 800 token/秒(Artificial Analysis)。在 BenchLeader Index 60 分及以上的模型中,Muse Spark 1.2 最快,约 210 token/秒。
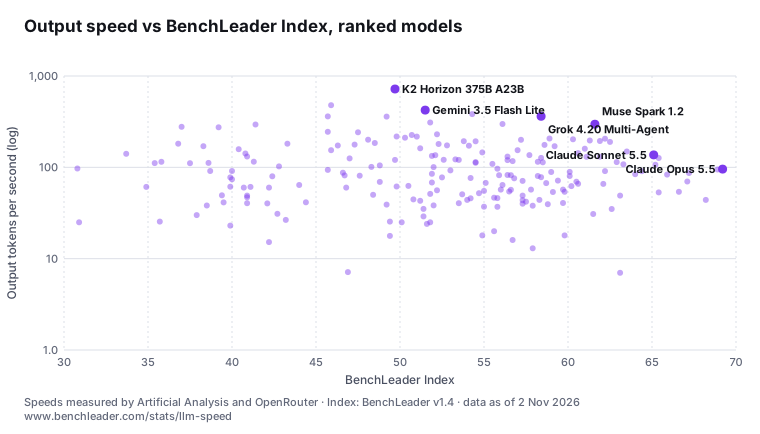
关键数据
每条数据都有独立链接(#),可直接引用。
- 已排名模型的输出速度中位数约为 82 token/秒,覆盖 210 个有速度测量值的已排名模型(由 Artificial Analysis 和 OpenRouter 测量;BenchLeader,2026年11月16日)。 #
- 首 token 延迟的中位数为 1.1 秒,覆盖 189 个已排名模型(由 OpenRouter 和 Artificial Analysis 测量;BenchLeader,2026年11月16日)。 #
- BenchLeader 追踪的最快模型是 Celeris 的 Celeris-1,约 800 token/秒(Artificial Analysis;BenchLeader,2026年11月16日)。 #
- 在 BenchLeader Index 60 分及以上的已排名模型中,最快的是 Muse Spark 1.2,约 210 token/秒(Artificial Analysis;BenchLeader,2026年11月16日)。 #
- 在 Index 60 分及以上的已排名模型中,首 token 延迟最低的是 Claude Opus 4.8,为 0.77 秒(OpenRouter;BenchLeader,2026年11月16日)。 #
- 在所有已排名模型中,首 token 延迟最低的是 Llama 3.2 3B Instruct,为 0.21 秒(OpenRouter;BenchLeader,2026年11月16日)。 #
- BenchLeader Index 第一名 Claude Fable 5.2 的输出速度约为 110 token/秒,首 token 延迟为 3.9 秒(输出速度由 Artificial Analysis 测量,首 token 延迟由 OpenRouter 测量;BenchLeader,2026年11月16日)。 #
各质量档位最快的模型
| Index 档位 | 有速度数据的模型 | 最快的模型 | token/秒 | 测量方 |
|---|---|---|---|---|
| 65+ | 10 | Claude Opus 5.5 Anthropic | 120 | Artificial Analysis |
| 60–65 | 27 | Muse Spark 1.2 Meta | 210 | Artificial Analysis |
| 55–60 | 55 | Grok 4.20 Multi-Agent SpaceXAI | 350 | OpenRouter |
| 50–55 | 42 | Muse Ember Meta | 440 | Artificial Analysis |
| 45–50 | 29 | Mercury 2 Inception | 350 | Artificial Analysis |
输出速度最快的模型
只列出已排名模型(有 BenchLeader Index 的模型)。速度排行榜还包括没有 Index 的模型,因此整体最快的模型可能不在这里。
| # | 模型 | Index | token/秒 | 测量方 |
|---|---|---|---|---|
| 1 | Muse Ember Meta | 52.1 | 440 | Artificial Analysis |
| 2 | Grok 4.20 Multi-Agent SpaceXAI | 58.5 | 350 | OpenRouter |
| 3 | Mercury 2 Inception | 49.2 | 350 | Artificial Analysis |
| 4 | Gemini 3.5 Flash Lite Google | 51.4 | 310 | Artificial Analysis |
| 5 | Gemini 3.1 Flash Lite Google | 52.6 | 300 | Artificial Analysis |
| 6 | Beam 1.0 Reflection | 45.9 | 290 | Artificial Analysis |
| 7 | Nemotron 3.5 Super VL NVIDIA | 45.8 | 270 | Artificial Analysis |
| 8 | Nemotron 3.5 Lightning NVIDIA | 41.4 | 270 | Artificial Analysis |
| 9 | Claude Haiku 5.5 Anthropic | 56.7 | 230 | Artificial Analysis |
| 10 | Nova Micro Amazon | 39.2 | 210 | Artificial Analysis |
首 token 延迟最低的模型
首 token 延迟最低的已排名模型;全部模型请看延迟排行榜。
| # | 模型 | Index | 首 token 延迟 | 测量方 |
|---|---|---|---|---|
| 1 | Llama 3.2 3B Instruct Meta | 35.6 | 0.21 秒 | OpenRouter |
| 2 | Llama 3.2 1B Instruct Meta | 30.6 | 0.23 秒 | OpenRouter |
| 3 | Command A+ Cohere | 45.9 | 0.23 秒 | OpenRouter |
| 4 | Nemotron 3 Ultra 550B A55B NVIDIA | 55.4 | 0.25 秒 | OpenRouter |
| 5 | Phi-4 Microsoft | 39.3 | 0.27 秒 | OpenRouter |
| 6 | Qwen3 30B A3B 2507 Alibaba | 48.0 | 0.28 秒 | OpenRouter |
| 7 | Nemotron 3.5 Lightning NVIDIA | 41.4 | 0.30 秒 | OpenRouter |
| 8 | Mistral Small 3 Mistral AI | 39.2 | 0.30 秒 | OpenRouter |
| 9 | GLM 4.7 Flash Zhipu AI | 51.0 | 0.31 秒 | OpenRouter |
| 10 | Granite 4.2 8B IBM | 41.1 | 0.31 秒 | OpenRouter |
这些数字是怎么得出的
输出速度是模型开始回答后每秒生成 token 数的中位数:Artificial Analysis 覆盖的模型采用其测得的中位数,其余采用 OpenRouter 实际流量的中位数(按 7 天平滑)。首 token 延迟在每张表中注明测量方;OpenRouter 的数据不包含思考阶段。中位数按已排名模型(有 BenchLeader Index 的模型)计算,取每个模型得分最高的配置。
速度取决于提供模型服务的提供商、负载和提示词,因此请把数字视为典型值而非保证值。完整的来源说明见方法说明。
引用这些数据
速度由 Artificial Analysis 和 OpenRouter 测量,此处注明来源展示;这些数据适用测量方的条款,不提供再使用。本页中 BenchLeader 自己的数据是 Index 分数和中位数。引用请使用下方的页面信息。
引用格式
BenchLeader,《大模型速度统计》,数据截至 2026年11月16日,https://www.benchleader.com/zh/stats/llm-speed。常见问题
- 大模型每秒能输出多少 token?
- BenchLeader 已排名模型的输出速度中位数约为 82 token/秒(由 Artificial Analysis 和 OpenRouter 测量)。追踪到的最快模型 Celeris-1 可达约 800 token/秒。
- 首 token 延迟一般是多少?
- 189 个已排名模型的中位数为 1.1 秒(由 OpenRouter 和 Artificial Analysis 测量)。OpenRouter 的首 token 数据不包含思考阶段。
- 最快的高质量大模型是哪个?
- Meta 的 Muse Spark 1.2:在 BenchLeader Index 60 分及以上的已排名模型中,约 210 token/秒(Artificial Analysis)。
- 这些速度数据从哪里来?
- 输出速度:Artificial Analysis 覆盖的模型采用其测得的中位数,其余采用 OpenRouter 实际流量的中位数(按 7 天平滑);首 token 延迟主要来自 OpenRouter。每个数字都注明测量方,并适用其使用条款;BenchLeader 不会再授权这些数据。