Which AI benchmarks are saturated?
Data as of 15 Nov 2026 · last updated · by BenchLeader
Of the 256 benchmarks BenchLeader tracks, 32 are saturated and 39 near-saturated: the top models score too close to the ceiling to tell apart. A percentage-scored board is saturated when its fifth-best model scores 90% or more; 163 boards are still active and 22 are retired (no new result for a year). Maths boards saturate most: 11 of 18.
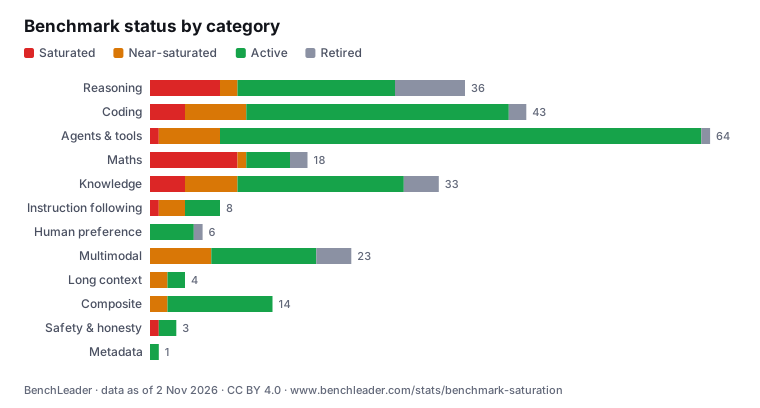
Key statistics
Each statistic has its own link (#) to cite it directly.
- Of the 256 benchmarks BenchLeader tracks, 32 are saturated, 39 near-saturated, 163 active and 22 retired (BenchLeader, 15 Nov 2026). #
- Maths has the largest share of saturated boards: 11 of 18 (BenchLeader, 15 Nov 2026). #
- GPQA Diamond is saturated: the fifth-best model scores 95.4% (BenchLeader, 15 Nov 2026). #
- ARC-AGI-2 is saturated: the fifth-best model scores 93.3% (BenchLeader, 15 Nov 2026). #
- Humanity's Last Exam is still active: the leader scores 54.8% (BenchLeader, 15 Nov 2026). #
- The hardest active boards with 10 or more models are Harvey LAB-AA v1.1 (best score 13.1%) and BTF-3 (best score 14.9%) (BenchLeader, 15 Nov 2026). #
Saturation by category
| Category | Saturated | Near-saturated | Active | Retired | Total |
|---|---|---|---|---|---|
| Reasoning | 9 | 3 | 16 | 8 | 36 |
| Coding | 3 | 9 | 30 | 2 | 44 |
| Agents & tools | 2 | 6 | 57 | 1 | 66 |
| Maths | 11 | – | 5 | 2 | 18 |
| Knowledge | 5 | 7 | 17 | 4 | 33 |
| Instruction following | 1 | 3 | 4 | – | 8 |
| Human preference | – | – | 5 | 1 | 6 |
| Multimodal | – | 7 | 12 | 4 | 23 |
| Long context | – | 2 | 2 | – | 4 |
| Composite | – | 2 | 12 | – | 14 |
| Safety & honesty | 1 | – | 2 | – | 3 |
| Metadata | – | – | 1 | – | 1 |
| All | 32 | 39 | 163 | 22 | 256 |
Saturated benchmarks (32)
The fifth-best model scores 90% or more. Each model counts once, at its best score.
Near-saturated benchmarks (39)
The leader is at 90% or more, or the fifth-best model at 80% or more.
Hardest active benchmarks
Active percentage-scored boards with results for 10 or more models, lowest leading score first.
| Benchmark | Category | Fifth-best | Leader | Leader score | Models |
|---|---|---|---|---|---|
| Harvey LAB-AA v1.1 | Agents & tools | 8.6% | Muse Wonder Full | 13.1% | 33 |
| BTF-3 | Reasoning | 14.1% | GLM 5.3 Flash | 14.9% | 13 |
| GDPx | Agents & tools | 9% | Claude Fable 5.2 | 16.4% | 21 |
| ProgramBench | Coding | 5.5% | Claude Fable 5.2 | 19% | 65 |
| CL-bench Life | Reasoning | 16.9% | GPT-5.5 | 22.2% | 17 |
| SciPredict | Reasoning | 22.2% | Gemini 3 Pro | 25.3% | 15 |
| Harvey's Legal Agent Benchmark v1 | Agents & tools | 19.6% | Muse Spark 1.2 | 25.4% | 80 |
| Harvey's Legal Agent Benchmark v1.1 | Agents & tools | 23.3% | Gemini 4 Argon | 27.1% | 37 |
| CL-bench | Reasoning | 20.8% | GPT-5.4 | 27.9% | 22 |
| BrowseComp | Agents & tools | 6.3% | Gemini 3.1 Pro | 31.2% | 41 |
What replaced them
For saturated and retired boards, the live benchmarks that test the same skill and still separate the top models.
- GPQA Diamond (AA) (saturated) → Humanity's Last Exam, CritPt
- τ²-Bench Telecom (AA) (saturated) → τ³-Banking (AA), Terminal-Bench
- GPQA Diamond (saturated) → Humanity's Last Exam, CritPt
- OTIS Mock AIME (saturated) → AIME 2026, FrontierMath Tiers 1–3
- ARC-AGI-1 (saturated) → ARC-AGI-2, ARC-AGI-3
- GPQA Diamond (Vals) (saturated) → Humanity's Last Exam, CritPt
- AIME (Vals) (saturated) → AIME 2026, FrontierMath Tiers 1–3
- MedQA (saturated) → MedScribe, AA-Omniscience v1.1
- MGSM (saturated) → FrontierMath Tiers 1–3, AIME 2026
- IFEval (HELM) (saturated) → IFBench, MultiChallenge
- MATH 500 (saturated) → FrontierMath Tiers 1–3, AIME 2026
- MMLU (retired) → MMLU-Pro, GPQA Diamond, Humanity's Last Exam
- MATH Level 5 (retired) → FrontierMath Tiers 1–3, HMMT February 2026
- ARC (AI2 Challenge) (retired) → ARC-AGI-2, GPQA Diamond
- WinoGrande (retired) → SimpleBench, Humanity's Last Exam
How these numbers are made
BenchLeader judges saturation only on percent-scored benchmarks with results for at least 10 models. Saturated: the fifth-best model (one score per model, its best) is at 90% or more, so the leaders are separated by noise. Near-saturated: the leader is at 90% or more, or the fifth-best at 80% or more. Retired: no new result for more than 365 days. Other benchmarks (Elo ratings, dollar amounts, small boards) are ‘active’ unless retired. Counts are benchmarks BenchLeader tracks from 47 publishers, not every benchmark published.
Some trackers call a benchmark saturated when the top model passes 90%. BenchLeader uses the fifth-best model, so one outlier result cannot saturate a board. The statuses are the same ones the benchmark catalogue shows.
Use this chart
These counts are BenchLeader's own and free to reuse under CC BY 4.0: credit BenchLeader with a link to this page. The benchmark scores in the tables and CSV remain under each benchmark publisher's own terms.
Embed code
<figure><a href="https://www.benchleader.com/stats/benchmark-saturation"><img src="https://www.benchleader.com/stats/benchmark-saturation.svg" alt="Of the 256 benchmarks BenchLeader tracks, 32 are saturated and 39 near-saturated: the top models score too close to the ceiling to tell apart." width="760"></a><figcaption>Source: <a href="https://www.benchleader.com/stats/benchmark-saturation">BenchLeader</a>, CC BY 4.0</figcaption></figure>Citation
BenchLeader, “AI benchmark saturation statistics”, data as of 15 Nov 2026, https://www.benchleader.com/stats/benchmark-saturation.Questions people ask
- What does it mean when a benchmark is saturated?
- The best models all score near the ceiling, so differences between them are noise. BenchLeader marks a percentage-scored board with 10 or more models saturated when its fifth-best model scores 90% or more, and near-saturated when the leader passes 90% or the fifth-best passes 80%.
- How many AI benchmarks are saturated?
- Of the 256 benchmarks BenchLeader tracks, 32 are saturated and 39 near-saturated: the top models score too close to the ceiling to tell apart. The rest: 163 active and 22 retired.
- Which AI benchmarks are hardest?
- Among active boards with 10 or more models, Harvey LAB-AA v1.1 (best score 13.1%) and BTF-3 (best score 14.9%).
- Why use the fifth-best model rather than the top score?
- Some trackers call a benchmark saturated when the top model passes 90%. BenchLeader uses the fifth-best model, so one outlier result cannot saturate a board.
Related: all benchmarks, methodology, BenchLeader Index, AI model release statistics, all statistics.